Should I Block AI Crawlers on My Business Website? What to Allow
We just saw AI bots crawling our website for the first time. Should we block them?
For most small businesses, no. Block the URLs that cost your server work, not the bots that can put you in ChatGPT, Claude and Perplexity answers. When AI crawlers pushed our own server to 100% CPU, one bot triggered 1,073 rebuilds of a single page in 23 hours. We still kept it allowed.
Why AI crawlers are suddenly showing up in your reports
Many owners, from a Zurich dental practice to a Lausanne architecture office, are only now seeing these visitors. Webflow’s LLM bot insights report shows which AI bots visit a site and which pages they request, based on the site’s server logs. It needs a Team or Enterprise plan with the Analyze add-on.
The report sorts bots into four groups: agentic bots that fetch a page to answer a user’s question, training bots, indexing bots, and bots with several purposes such as Googlebot and Bingbot. One detail saves a worried email. /manifest.json often appears among the most-visited paths, and Webflow says this is expected and unrelated to your content. The report also does not tell you whether a page was cited in an AI answer. It only shows that a bot asked for it.
Not all AI crawlers do the same job
“AI crawler” covers three different kinds of visitor, and each gets its own rule in robots.txt, the plain text file that tells bots what they may read. OpenAI states that each setting is independent. You can allow its search bot so you appear in results while blocking its training bot.
| Bot type | Examples | What it does | What blocking it means |
|---|---|---|---|
| Search and indexing | OAI-SearchBot, Claude-SearchBot, PerplexityBot | Finds pages to show and link in AI search answers | OpenAI: your site is not shown in ChatGPT search answers, though it can still appear as a navigational link. Anthropic: your content is not indexed for Claude’s search. |
| User-triggered | ChatGPT-User, Claude-User, Perplexity-User | Fetches a page when a person asks a question | Anthropic: Claude cannot retrieve your page for that user. OpenAI and Perplexity say robots.txt rules may not apply, because a person started the fetch. |
| Training | GPTBot, ClaudeBot, Google-Extended | Collects content that may train future AI models | Signals that your future content should be left out of training. It does not remove you from search. |
Anthropic’s help page gives the same split for its three bots and says they follow robots.txt. Perplexity says PerplexityBot is not used to train foundation models and recommends allowing it. Google-Extended is a special case. It has no user agent of its own and only controls how Google may use content for Gemini. Google says it does not affect inclusion in Google Search and is not a ranking signal.
When to allow AI crawlers
Allow the search and user-triggered bots if you want to be named in AI answers. These are the bots that read your page when someone asks ChatGPT or Perplexity for a recommendation in your field. Block them and you drop out of that answer. If you are unsure where you stand today, start by checking whether ChatGPT already recommends your business.
Allow them too if your pages are marketing pages: services, prices, team, case studies. Those pages exist to be read. We made this call for our own site. Our robots.txt still says yes to search, AI answers and AI training, because we want ChatGPT, Claude and Perplexity to read our pages and cite us.
When to block, and what exactly
Block training bots if your content is the product you sell, such as paid guides or research, and you do not want it used to build AI models. Because the rules are independent, blocking GPTBot or Google-Extended does not take you out of ChatGPT search or Google Search.
Block URL variants that create server work without adding content. Filter, tag and page-number links can turn one page into hundreds of addresses. A crawler that follows them all is doing nothing wrong, but your server pays for every visit.
Slow a heavy bot down before you shut it out. Anthropic supports the Crawl-delay rule for ClaudeBot. It was the only provider in the docs we read to mention it.
Avoid blocking by IP address. Anthropic warns that this may not work as an opt-out, because the bot can no longer read your robots.txt. User agent names can also be faked, as Google points out, so a bot calling itself GPTBot may not be OpenAI. If you use Cloudflare, Perplexity notes that Bot Fight Mode can still challenge its bots, and recommends firewall rules that match both user agent and IP. Changes are not instant either. OpenAI and Perplexity both mention around 24 hours.
What happened when AI crawlers overloaded our own server
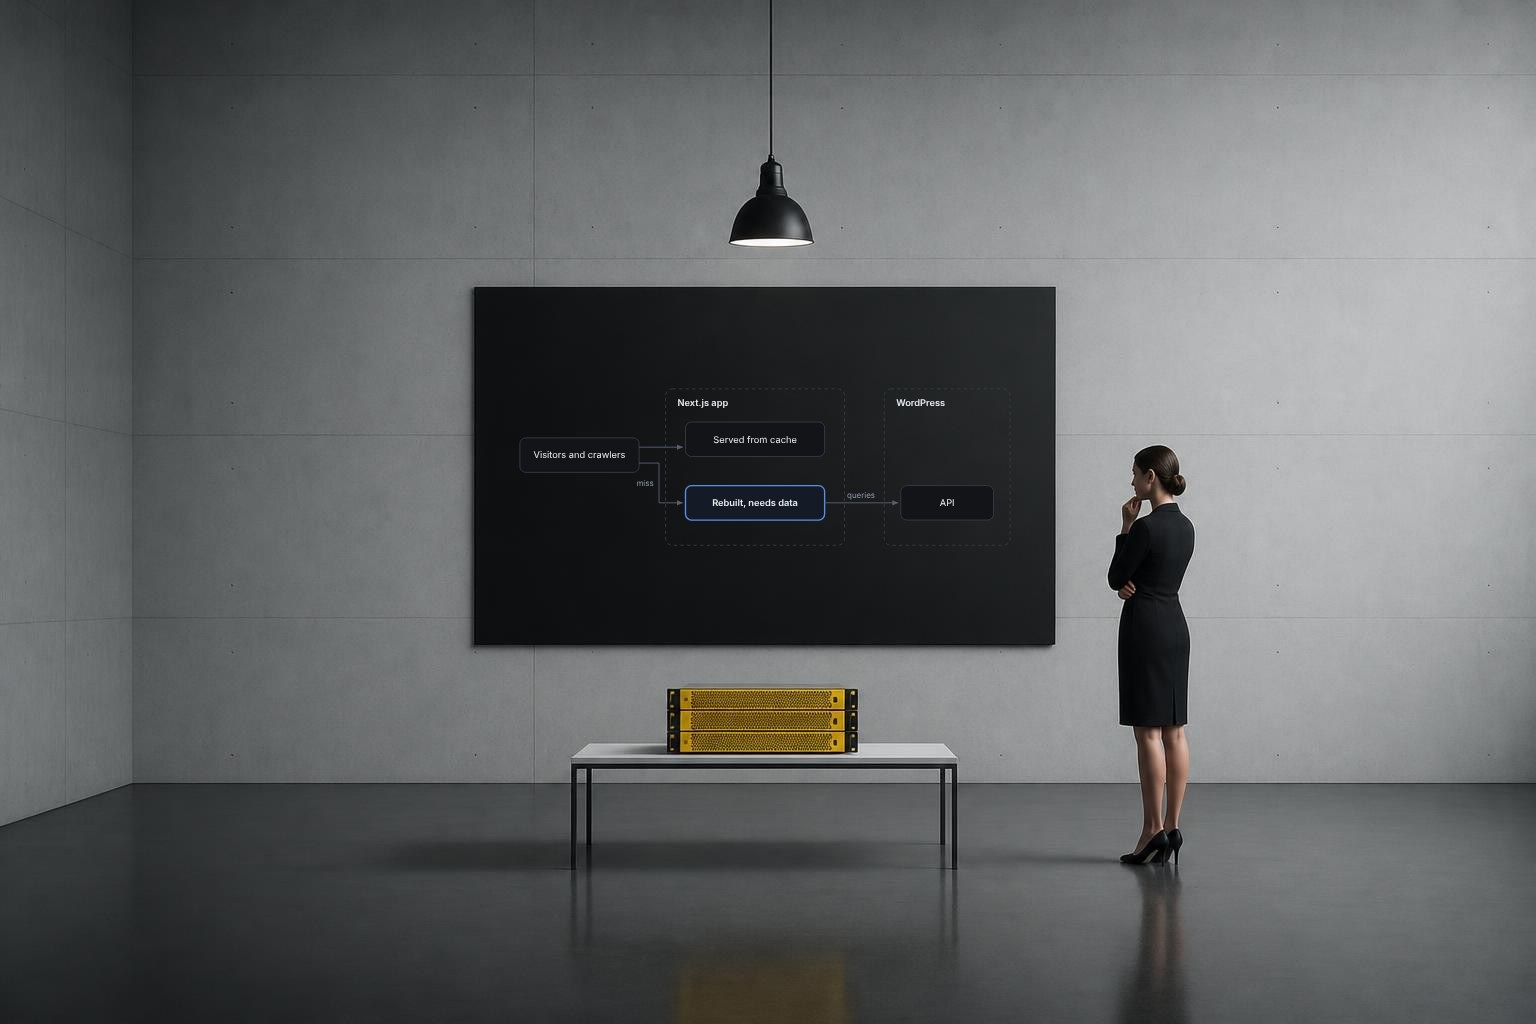
This month our WordPress server kept hitting 100% CPU, once for 40 minutes. Our host saw about 2,400 requests a day and suspected a script. The logs showed otherwise: most of the load came from AI crawlers. In 23 hours, our blog list was rebuilt 1,344 times, and 1,073 of those rebuilds were for ClaudeBot. It followed every ?page= and ?tag= link, and our site rebuilt that page on every visit.
We did not block the AI bots. We blocked only the ?page= and ?tag= variants and gave ClaudeBot a crawl delay of 10 seconds. Search engines still find every post through the sitemap. We also keep an llms.txt file that tells AI tools who we are and links to our main pages. With four other small fixes, this was the result:
| Metric | Before | After |
|---|---|---|
| Requests per day | 2,400+ | 176 |
| CPU faults | Repeated, once 40 minutes at 100% | Stopped |
| AI bots allowed for search, answers and training | Yes | Yes |
Should I block AI crawlers on my business website? A five-step check
- Open your bot report and list the pages AI bots request most. In Webflow: Insights, Site overview, AI discovery tab, LLM bots.
- Check whether those pages are cached or rebuilt on every visit.
- Block junk URL variants such as filters, tags and page numbers before you think about blocking a bot.
- Decide on AI training separately from search and answers, since each has its own rule.
- If one bot is still too heavy, slow it with Crawl-delay where the provider supports it, or write to the provider from an address on your domain, as Anthropic asks.
Most of these decisions belong in the build, not in a panic after a server alarm. A site made for AI-era search ships with a clean robots.txt, a sitemap, cached pages and an llms.txt file, and someone checks the bot reports after launch. Our guide to SEO, GEO and AEO strategy (ranking in search engines and getting cited by AI tools) shows where crawler access fits. To see where your own site stands, run Pixerry’s free site check. It reads your site the way search and AI engines do.